Tag: Event time processing

  • Presentation: Stream and Batch Processing Convergence in Apache Flink

    Title: The Convergence of Stream and Batch Processing in Apache Flink: A Comprehensive Overview by Jiangjie Qin

    Apache Flink has been at the forefront of revolutionizing data processing, offering a unified platform that seamlessly integrates both stream and batch processing. In a recent presentation by Jiangjie Qin, the motivations and compelling use cases for this convergence were eloquently outlined, shedding light on the intricate workings of Apache Flink.

    One of the key aspects emphasized by Jiangjie Qin is how Apache Flink bridges the gap between stream and batch processing by unifying computing models. This unification is achieved through shared streaming semantics, enabling developers to leverage a consistent framework regardless of the processing type – stream or batch.

    Moreover, Flink’s adeptness at adapting execution models for optimal efficiency was highlighted in the presentation. By dynamically adjusting its execution strategy based on the workload and requirements, Flink ensures that resources are utilized judiciously, leading to enhanced performance and throughput.

    A standout feature of Apache Flink, as underscored by Qin, is its robust handling of event time and watermarks in processing data streams. By effectively managing event time semantics and watermarks, Flink guarantees accuracy and reliability in stream processing, a critical capability for real-time analytics and decision-making.

    Additionally, Jiangjie Qin delved into the nuances of state management in batch processing within Apache Flink. The platform’s ability to maintain and manipulate state efficiently in batch operations contributes to the seamless convergence of stream and batch processing, offering developers a comprehensive toolkit for diverse data processing requirements.

    Looking ahead, Jiangjie Qin outlined the roadmap for Apache Flink, envisioning a future where data processing is even more seamless and performant. By continually refining its capabilities and addressing emerging challenges, Flink aims to provide users with an unparalleled data processing experience that is both efficient and scalable.

    In conclusion, Jiangjie Qin’s insightful presentation on the convergence of stream and batch processing in Apache Flink offers a comprehensive understanding of the platform’s capabilities and vision. As Apache Flink continues to evolve and innovate, it remains a compelling choice for organizations seeking a versatile and high-performance solution for their data processing needs.
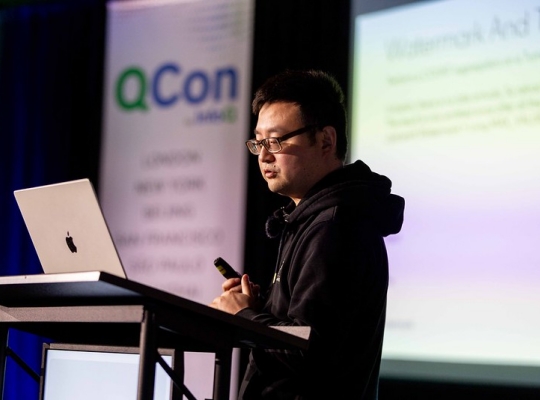
  • Presentation: Stream and Batch Processing Convergence in Apache Flink

    Title: The Fusion of Stream and Batch Processing in Apache Flink: A Comprehensive Overview by Jiangjie Qin

    Apache Flink, a powerful open-source stream processing framework, has been making waves in the industry with its seamless integration of stream and batch processing capabilities. In a recent presentation by Jiangjie Qin, the convergence of these two processing paradigms in Apache Flink was thoroughly explored, highlighting the motivations behind this unification and its practical applications in real-world scenarios.

    One of the key aspects emphasized by Qin is how Apache Flink unifies computing models through shared streaming semantics. By bridging the gap between stream and batch processing, Flink enables developers to leverage a consistent programming model for both types of data processing tasks. This convergence not only simplifies the development process but also enhances the flexibility and scalability of data processing pipelines.

    Moreover, Qin delves into how Flink adapts its execution models to ensure optimal efficiency when handling both streaming and batch data. By optimizing resource utilization and task scheduling, Flink can deliver high-performance processing capabilities while maintaining low latency and high throughput. This adaptability is crucial for meeting the diverse requirements of modern data-driven applications.

    In his presentation, Qin also sheds light on Flink’s sophisticated handling of event time and watermarks, essential components for ensuring data consistency and correctness in stream processing. By providing robust mechanisms for event-time processing, Flink empowers developers to build reliable and fault-tolerant streaming applications that can process data with temporal dependencies accurately.

    Furthermore, Qin discusses the integration of state management in batch processing within the Flink framework. By incorporating stateful processing capabilities into batch jobs, Flink enables developers to work with complex data transformations and aggregations seamlessly. This integration not only streamlines the development process but also enhances the performance and reliability of batch processing tasks.

    Looking ahead, Qin outlines the future work planned for Apache Flink to deliver an even more seamless and performant data processing experience. By focusing on enhancing the scalability, fault tolerance, and usability of the framework, Flink aims to empower developers to tackle increasingly complex data processing challenges with ease.

    In conclusion, Jiangjie Qin’s insightful presentation on the convergence of stream and batch processing in Apache Flink underscores the significance of unified data processing models in modern IT and software development. By embracing the capabilities of Flink, developers can unlock new possibilities for building robust, efficient, and scalable data processing pipelines that meet the demands of today’s data-driven ecosystem.

    For more information on Apache Flink and its innovative stream and batch processing convergence, you can access Jiangjie Qin’s full presentation here.

  • Real-Time AI Apps: Using Apache Flink for Model Inference

    Real-Time AI Apps: Using Apache Flink for Model Inference

    In today’s fast-paced digital landscape, businesses are constantly challenged to process vast amounts of data swiftly, all while making critical decisions in real time. This demand has led to the rise of real-time AI applications that can analyze data streams instantaneously to extract valuable insights. Apache Flink has emerged as a powerful tool for enabling real-time data processing and model inference, revolutionizing the way organizations harness the power of artificial intelligence.

    Apache Flink, known for its low-latency and high-throughput processing capabilities, is an open-source stream processing framework that excels in handling continuous data streams with efficiency and speed. By leveraging Apache Flink for model inference, businesses can achieve near-instantaneous predictions and responses based on incoming data, enhancing their operational agility and competitive edge.

    One of the key advantages of using Apache Flink for real-time AI applications is its ability to seamlessly integrate with existing AI and machine learning models. This integration allows organizations to deploy and execute complex machine learning algorithms in real time, enabling them to adapt quickly to changing data patterns and optimize decision-making processes on the fly.

    Additionally, Apache Flink offers robust state management capabilities, ensuring fault tolerance and consistency in real-time data processing. This feature is crucial for maintaining data integrity and reliability, especially when dealing with large-scale data streams where accuracy and consistency are paramount.

    Moreover, Apache Flink provides support for event time processing, allowing businesses to analyze data based on the time at which events occurred rather than when they are processed. This functionality is essential for applications requiring precise temporal analysis, such as fraud detection, IoT data processing, and financial trading systems.

    By harnessing the power of Apache Flink for real-time AI model inference, organizations can unlock a myriad of benefits, including:

    • Improved Decision-Making: Real-time AI applications powered by Apache Flink enable businesses to make data-driven decisions instantaneously, enhancing operational efficiency and strategic planning.
    • Enhanced Customer Experience: By analyzing data streams in real time, organizations can personalize customer interactions, offer targeted recommendations, and respond promptly to changing customer needs.
    • Optimized Resource Allocation: Real-time model inference with Apache Flink allows businesses to allocate resources dynamically based on real-time insights, optimizing efficiency and reducing operational costs.
    • Scalability and Flexibility: Apache Flink’s distributed processing architecture enables seamless scalability to handle increasing data volumes, ensuring that organizations can adapt to evolving business requirements.

    In conclusion, Apache Flink stands out as a powerful framework for enabling real-time AI applications and model inference, empowering businesses to extract actionable insights from data streams instantaneously. By incorporating Apache Flink into their AI infrastructure, organizations can achieve unparalleled speed, accuracy, and efficiency in processing real-time data, ultimately driving innovation and competitive advantage in today’s dynamic business environment.