Tag: architecture visualization

  • 7 Python Libraries Every Analytics Engineer Should Know

    In the world of analytics engineering, Python libraries play a crucial role in simplifying tasks related to data cleaning, transformation, and analysis. As an analytics engineer, having a good grasp of these tools can significantly enhance your productivity and efficiency. Let’s take a quick look at seven essential Python libraries that every analytics engineer should be familiar with:

    • Pandas: Pandas is a powerful library for data manipulation and analysis. It provides data structures like dataframes that are ideal for handling structured data. With Pandas, you can easily filter, group, and aggregate data, making it a must-have tool for any analytics engineer working with tabular data.
    • NumPy: NumPy is another fundamental library for numerical computing in Python. It offers support for large multi-dimensional arrays and matrices, along with a collection of mathematical functions to operate on these arrays. NumPy is essential for tasks that involve numerical computations, such as linear algebra operations and statistical analysis.
    • Matplotlib: Visualization is key in data analysis, and Matplotlib is a go-to library for creating static, animated, and interactive plots in Python. Whether you need to generate simple line charts or complex 3D visualizations, Matplotlib provides the flexibility and customization options required to communicate your findings effectively.
    • Seaborn: Seaborn is built on top of Matplotlib and offers a higher-level interface for creating attractive and informative statistical graphics. It simplifies the process of visualizing complex relationships in data through features like built-in themes, color palettes, and functions for plotting categorical data. For analytics engineers looking to create visually appealing plots with minimal effort, Seaborn is a valuable asset.
    • Scikit-learn: When it comes to machine learning in Python, Scikit-learn stands out as a versatile and user-friendly library. It provides a wide range of algorithms for classification, regression, clustering, and more, along with tools for model selection and evaluation. Analytics engineers can leverage Scikit-learn to build and deploy machine learning models for predictive analytics tasks.
    • Statsmodels: For statistical modeling and hypothesis testing, Statsmodels is a comprehensive library that offers a rich set of tools and algorithms. From linear regression to time series analysis, Statsmodels covers a broad spectrum of statistical methods commonly used in data analysis. Analytics engineers can rely on Statsmodels to perform detailed statistical tests and derive meaningful insights from their data.
    • TensorFlow: As a library primarily focused on deep learning, TensorFlow is indispensable for analytics engineers working on advanced predictive modeling and neural network applications. With TensorFlow, you can design, train, and deploy deep learning models efficiently, thanks to its scalable architecture and extensive set of tools. Whether you’re building image recognition systems or natural language processing models, TensorFlow provides the resources needed to tackle complex machine learning projects.

    In conclusion, these seven Python libraries form the backbone of a well-rounded analytics engineer’s toolkit, enabling them to clean, transform, and analyze data effectively. By mastering these libraries and understanding their capabilities, analytics engineers can streamline their workflows, uncover valuable insights, and drive data-driven decision-making within their organizations. So, whether you’re just starting out in the field or looking to enhance your skill set, familiarizing yourself with these essential Python libraries is a worthwhile investment in your professional development.
  • Think in Graphs, Not Just Chains: JGraphlet for TaskPipelines

    Title: Transform Your Approach: Enhance Task Pipelines with JGraphlet

    In the realm of Java development, efficiency and scalability are paramount considerations. While traditional linear chains have their place, embracing a graph-based approach can revolutionize how task pipelines are structured and managed. Enter JGraphlet, a compact yet robust library that champions the power of graphs in Java development.

    JGraphlet stands out in the crowded landscape of Java libraries by offering a refreshing take on building task pipelines. Unlike its counterparts that boast extensive feature lists, JGraphlet derives its strength from a concise set of core design principles that seamlessly intertwine to deliver exceptional functionality.

    Central to JGraphlet’s philosophy is the concept of simplicity, embodied by its core component, the Graph. By leveraging JGraphlet, developers can effortlessly construct task pipelines by adding tasks and establishing connections to form a graph structure. Each task within this graph is equipped with defined input and output parameters, facilitating a clear and structured flow of data.

    At the crux of JGraphlet’s capabilities lies the TaskPipeline, a pivotal entity responsible for orchestrating the execution of the pipeline while adeptly managing the input and output operations for each task. This streamlined approach not only enhances the overall efficiency of task execution but also simplifies the complexities associated with data flow management in Java applications.

    One of the standout features of JGraphlet is its emphasis on eliminating dependencies, offering a lightweight solution that minimizes the burden on developers. This zero-dependency characteristic not only streamlines the integration process but also ensures that the library remains agile and adaptable to diverse project requirements.

    Moreover, JGraphlet’s intuitive design empowers developers to visualize and manipulate task pipelines with ease, fostering a more intuitive and streamlined development experience. By embracing a graph-based paradigm, developers can gain a deeper understanding of the relationships between tasks, paving the way for optimized pipeline design and execution.

    In practical terms, the versatility of JGraphlet transcends conventional task management approaches, offering developers a flexible toolkit to tackle a myriad of complex scenarios. Whether navigating intricate data processing workflows or optimizing computational tasks, JGraphlet equips developers with the tools needed to enhance productivity and streamline development processes.

    By embracing JGraphlet for task pipeline management, developers can unlock a world of possibilities in Java development. From simplifying pipeline design to optimizing task execution, JGraphlet serves as a catalyst for innovation, enabling developers to transcend traditional linear constraints and embrace the dynamic potential of graph-based workflows.

    In conclusion, JGraphlet represents a paradigm shift in task pipeline management, urging developers to think in graphs rather than chains. By harnessing the power of graphs through JGraphlet, developers can elevate their Java development practices to new heights, fostering efficiency, scalability, and innovation in equal measure.

  • Beginner’s Guide to Data Analysis with Polars

    Title: Mastering Data Analysis with Polars: A Beginner’s Comprehensive Guide

    In the realm of data analysis, speed and scalability are paramount. This is where Polars, a lightning-fast DataFrame library, shines. Tailored for swift and efficient data manipulation, Polars is the go-to tool for professionals seeking quick insights from vast datasets. For beginners looking to harness the power of Polars, this comprehensive guide will pave the way for a seamless journey into the world of data analysis.

    Understanding the Basics

    At its core, Polars simplifies data analysis by offering a familiar DataFrame structure akin to other popular libraries like Pandas. This familiarity makes the transition smooth for those well-versed in data manipulation tools. What sets Polars apart is its exceptional speed and scalability, enabling users to process massive datasets with ease. By leveraging Rust’s performance benefits, Polars ensures that your data analysis tasks are completed swiftly, even when dealing with extensive data volumes.

    Getting Started with Polars

    To embark on your Polars journey, the first step is to install the library. Whether you prefer using pip for Python or adding Polars to your Rust project, the installation process is straightforward. Once installed, creating a DataFrame in Polars is as simple as loading data from a CSV file or directly inputting data. This seamless data input mechanism allows beginners to dive into analysis without hassle.

    Exploring Data with Polars

    One of the key aspects of data analysis is exploration. Polars equips users with a range of functions to delve deep into their datasets. From filtering and grouping to sorting and aggregating, Polars offers a plethora of tools to dissect and understand your data better. For beginners, these functions serve as building blocks to construct insightful analyses and draw valuable conclusions.

    Optimizing Performance

    In the realm of data analysis, performance is non-negotiable. Polars’ efficient design ensures that your data operations are executed swiftly, even when dealing with extensive datasets. By harnessing parallel processing and leveraging Rust’s speed, Polars optimizes performance, providing users with rapid results for their analytical queries. This means you can focus on deriving insights rather than waiting for computations to complete.

    Visualization and Interpretation

    Data analysis is incomplete without visualization. Polars seamlessly integrates with popular visualization libraries like Matplotlib and Plotly, enabling users to create stunning visual representations of their data. Whether you’re crafting interactive plots or generating insightful graphs, Polars’ integration with visualization tools enhances the storytelling aspect of your data analysis journey. This means you can present your findings in a compelling and visually engaging manner.

    Advanced Features and Beyond

    As you progress in your data analysis endeavors, Polars offers a host of advanced features to cater to your evolving needs. From window functions and joins to custom aggregations and data transformations, Polars provides a robust toolkit for professionals seeking to elevate their analyses. By mastering these advanced features, users can unlock the full potential of Polars and leverage its capabilities to tackle complex data analysis challenges effectively.

    Conclusion

    In conclusion, Polars stands out as a versatile and efficient DataFrame library that empowers users to conduct quick, scalable data analysis. For beginners venturing into the world of data analysis, Polars serves as an invaluable tool, offering a seamless experience from data input to visualization. By mastering the basics, exploring data insights, optimizing performance, and leveraging advanced features, users can harness the full potential of Polars for their analytical endeavors. So, why wait? Dive into the world of data analysis with Polars and unlock a realm of possibilities for your data-driven projects.

  • Mastering Digital Breadcrumbs to Stay Ahead of Evolving Threats

    In the ever-evolving landscape of cybersecurity, digital breadcrumbs play a crucial role in unraveling the mysteries of cyber threats. Mastering the art of following these digital trails can be the key to staying ahead of malicious actors and protecting sensitive information. For cybersecurity professionals, delving into the realm of digital forensics offers a challenging yet immensely rewarding career path. By investing in specialized knowledge and committing to continuous learning, professionals can sharpen their skills in tracing, analyzing, and interpreting digital breadcrumbs to mitigate risks effectively.

    Digital breadcrumbs, in the context of cybersecurity, refer to the traces left behind by users as they interact with digital systems. These traces can take various forms, including log files, metadata, cookies, timestamps, and network traffic. Analyzing these breadcrumbs can provide invaluable insights into the activities of users, potential security incidents, and indicators of compromise. By mastering the techniques of collecting, preserving, and analyzing digital evidence, cybersecurity professionals can reconstruct events, identify vulnerabilities, and attribute security incidents to specific threat actors.

    One of the fundamental aspects of mastering digital breadcrumbs is understanding the importance of proper documentation and chain of custody. When collecting digital evidence, professionals must follow strict protocols to ensure that the integrity of the evidence is preserved. Any misstep in the collection or preservation process can compromise the admissibility of the evidence in legal proceedings, undermining the entire investigation. By adhering to industry best practices and standards, such as those outlined by the International Organization on Computer Evidence (IOCE) and the National Institute of Standards and Technology (NIST), cybersecurity professionals can maintain the credibility and reliability of the digital evidence they gather.

    Moreover, mastering digital breadcrumbs requires a deep understanding of various forensic tools and techniques. Cybersecurity professionals must be proficient in using tools such as EnCase, FTK, Autopsy, and Volatility to extract, analyze, and interpret digital evidence effectively. These tools enable professionals to uncover hidden artifacts, recover deleted files, and reconstruct timelines of events, offering valuable insights into the tactics, techniques, and procedures employed by threat actors. By staying abreast of the latest advancements in forensic tools and techniques, professionals can enhance their investigative capabilities and adapt to the evolving nature of cyber threats.

    Furthermore, mastering digital breadcrumbs entails honing skills in data analysis, correlation, and visualization. Cybersecurity professionals must be adept at analyzing large volumes of data from disparate sources, correlating relevant information, and presenting findings in a clear and concise manner. Visualization techniques, such as timelines, link analysis, and geospatial mapping, can help professionals identify patterns, connections, and anomalies that may go unnoticed through traditional analysis methods. By harnessing the power of data analytics and visualization, cybersecurity professionals can uncover actionable intelligence, strengthen defenses, and proactively respond to emerging threats.

    In conclusion, mastering digital breadcrumbs is essential for cybersecurity professionals looking to stay ahead of evolving threats in today’s digital landscape. By investing in specialized knowledge, continuous learning, and hands-on experience in digital forensics, professionals can enhance their investigative skills, mitigate risks, and protect critical assets from cyber attacks. By following best practices, leveraging forensic tools, and honing data analysis techniques, cybersecurity professionals can effectively trace, analyze, and interpret digital breadcrumbs to uncover the truth behind security incidents and bolster their organizations’ cybersecurity posture.

  • How to Make OpenTelemetry Better in the Browser

    In the realm of web development, OpenTelemetry stands out as a powerful tool for observability, allowing developers to gain insights into the performance of their applications. However, when it comes to utilizing OpenTelemetry in the browser, there are certain challenges that can make the process less than seamless. In this article, we will explore some strategies to enhance the usability and effectiveness of OpenTelemetry in the browser environment.

    One key aspect to consider when working with OpenTelemetry in the browser is the need for efficient data collection. Since browsers have limitations compared to server-side environments, it’s crucial to optimize the way data is gathered to minimize performance overhead. Leveraging sampling techniques can help reduce the volume of data collected, ensuring that the impact on the application’s performance is minimal.

    Moreover, integrating OpenTelemetry with other monitoring tools commonly used in frontend development, such as browser performance APIs or error tracking services, can provide a more comprehensive view of the application’s behavior. By correlating data from these different sources, developers can quickly identify and troubleshoot issues that may arise in the frontend.

    Another area where OpenTelemetry can be enhanced in the browser is through improved visualization capabilities. Utilizing libraries like Grafana or integrating with existing dashboard solutions can help create insightful visual representations of the collected data. These visualizations not only make it easier to interpret the performance metrics but also enable teams to spot trends and anomalies more effectively.

    Furthermore, ensuring compatibility with various frameworks and libraries commonly used in frontend development is essential for the widespread adoption of OpenTelemetry in the browser. Providing clear documentation and easy-to-use plugins for popular frameworks like React, Angular, or Vue.js can lower the barrier to entry for developers looking to incorporate observability into their frontend applications.

    In conclusion, by optimizing data collection, integrating with other monitoring tools, enhancing visualization capabilities, and ensuring compatibility with frontend frameworks, OpenTelemetry can be made significantly better in the browser. These improvements not only streamline the observability process but also empower developers to build more robust and performant web applications. By embracing these strategies, developers can unlock the full potential of OpenTelemetry in the frontend development landscape.

  • Hugging Face Releases Trackio, a Lightweight Open-Source Experiment Tracking Library

    Hugging Face, a leading figure in the AI community, has recently unveiled Trackio, a cutting-edge open-source Python library geared toward simplifying experiment tracking. Trackio promises a seamless experience, boasting a lightweight design that ensures ease of integration. Unlike its counterparts, Trackio shines by offering local dashboards as a default feature, enabling users to monitor experiments effortlessly.

    Experiment tracking is a crucial aspect of any data science project, allowing developers to keep tabs on various iterations and fine-tune their models effectively. With Trackio, this process becomes not only manageable but also transparent. Its user-friendly interface is designed to streamline the tracking process, ensuring that developers can focus on refining their models without getting bogged down in complex tracking procedures.

    One of the standout features of Trackio is its compatibility with Hugging Face Spaces, facilitating seamless synchronization for sharing and collaboration. This integration enhances the collaborative aspect of data science projects, enabling team members to work together efficiently regardless of their physical locations. By leveraging Trackio’s capabilities, developers can foster a more cohesive and productive working environment, ultimately leading to better outcomes for their projects.

    Moreover, Trackio serves as a compelling alternative to existing solutions like Weights & Biases (wandb). Its emphasis on simplicity and transparency sets it apart in the landscape of experiment tracking tools. By offering local dashboards by default, Trackio empowers developers to visualize their experiments without the need for additional configurations, thereby saving time and streamlining the workflow.

    In today’s fast-paced world of AI and machine learning, having access to tools like Trackio can make a significant difference in the efficiency and success of data science projects. By simplifying the experiment tracking process and promoting collaboration, Trackio equips developers with the resources they need to drive innovation and achieve their goals effectively.

    In conclusion, Hugging Face’s release of Trackio represents a significant milestone in the realm of experiment tracking libraries. Its lightweight design, transparent interface, and seamless integration with Hugging Face Spaces make it a valuable asset for developers looking to enhance their data science workflows. As the demand for efficient and user-friendly tools continues to grow, Trackio stands out as a promising solution that embodies simplicity, transparency, and collaboration in the ever-evolving field of AI and machine learning.

  • MCP-UI Creators on Why AI Agents Need Rich User Interfaces

    In the rapidly evolving landscape of artificial intelligence (AI), the importance of user interfaces cannot be overstated. The creators of MCP-UI, a groundbreaking open-source project, have shed light on why AI agents benefit greatly from rich user interfaces. This innovative initiative provides a seamless way to integrate web-based UI components into AI agents, enhancing their functionality and user experience.

    AI agents, with their advanced capabilities in machine learning and natural language processing, have become integral parts of various industries, from customer service to healthcare. However, the effectiveness of these AI agents heavily relies on the quality of their user interfaces. A rich user interface not only improves the interaction between users and AI systems but also enhances usability and accessibility.

    One of the key reasons why AI agents need rich user interfaces is to facilitate intuitive communication. By incorporating visually engaging elements such as interactive charts, graphs, and animations, users can better comprehend complex data and insights generated by AI algorithms. This visual representation makes the information more digestible and actionable, leading to more informed decision-making.

    Moreover, rich user interfaces play a crucial role in building trust and rapport with users. When AI agents present information in a clear and visually appealing manner, users are more likely to trust the recommendations and insights provided. This trust is essential for fostering long-term relationships between users and AI systems, ultimately driving user engagement and satisfaction.

    Additionally, rich user interfaces can streamline the user experience by simplifying navigation and reducing cognitive load. Features like drag-and-drop functionality, auto-suggestions, and customizable dashboards empower users to interact with AI agents effortlessly. This level of interactivity not only enhances user productivity but also contributes to a more enjoyable and engaging user experience.

    Furthermore, rich user interfaces enable personalization and customization, allowing users to tailor their interactions with AI agents according to their preferences and needs. By offering features like theme customization, language preferences, and personalized recommendations, AI agents can deliver a personalized experience that resonates with individual users, leading to higher levels of user retention and satisfaction.

    In conclusion, the creators of MCP-UI have highlighted the significant impact of rich user interfaces on the effectiveness and adoption of AI agents. By integrating web-based UI components into AI systems, organizations can enhance communication, build trust, streamline user experience, and enable personalization. As AI continues to revolutionize industries, investing in rich user interfaces is crucial for maximizing the potential of AI agents and delivering exceptional user experiences.

    Image Source: The New Stack

  • DeepMind Launches Genie 3, a Text-to-3D Interactive World Model

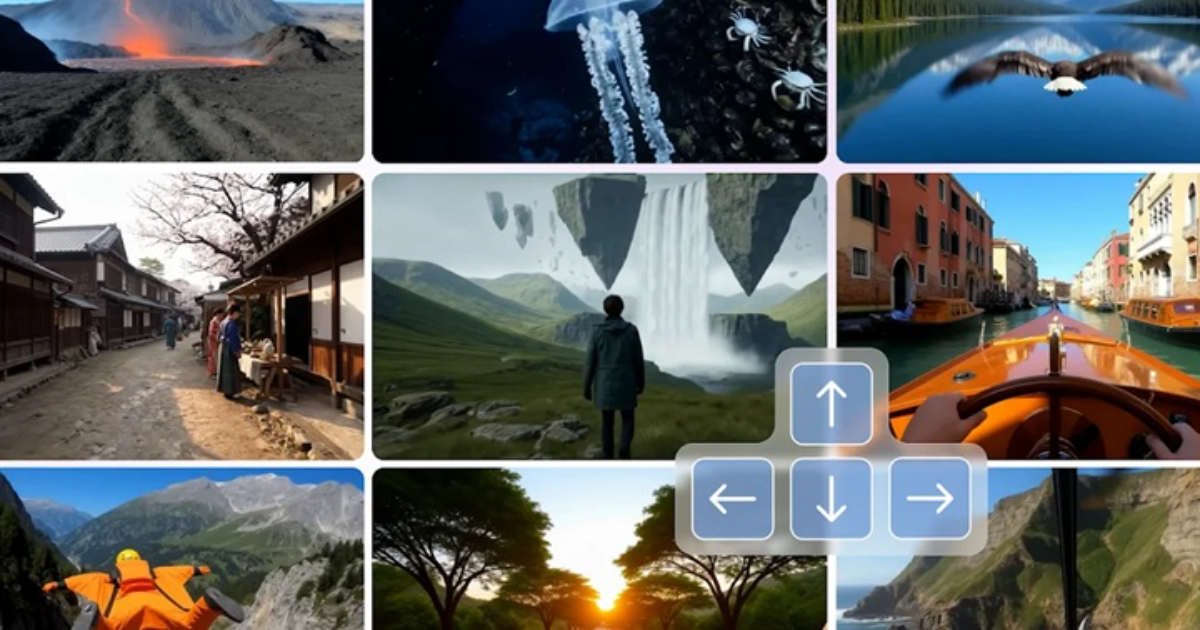
    !DeepMind Genie 3

    DeepMind, the pioneering artificial intelligence (AI) research lab, continues to push the boundaries of what’s possible in the realm of AI with the launch of Genie 3. This latest iteration represents a significant leap forward in the field of text-to-3D interactive world modeling.

    Genie 3 is built upon DeepMind’s innovative “world model” framework, which now enables the generation of immersive 3D environments directly from text inputs. Imagine being able to describe a scene in words, and then seeing it come to life in three-dimensional space through the magic of AI – that’s the power of Genie 3.

    One of the remarkable aspects of Genie 3 is its ability to understand and interpret natural language descriptions, allowing users to effortlessly create complex virtual worlds with simple text prompts. This opens up a world of possibilities for creators, developers, and storytellers looking to bring their ideas to life in a tangible and interactive way.

    For example, a user could input a description like “a lush forest with a winding river and a majestic waterfall,” and Genie 3 would generate a detailed 3D representation of this scene, complete with trees, water features, and realistic lighting effects. This kind of technology has far-reaching implications across various industries, from gaming and entertainment to architecture and urban planning.

    Moreover, Genie 3’s interactive capabilities mean that users can not only visualize but also interact with the generated 3D environments in real-time. This level of immersion and engagement opens up new avenues for exploration, experimentation, and creativity in virtual spaces.

    The potential applications of Genie 3 are vast and varied. Game developers can use this technology to rapidly prototype and iterate on game worlds, architects can visualize their designs in a more intuitive way, and educators can create interactive simulations for immersive learning experiences. The only limit is the imagination of the user.

    In conclusion, DeepMind’s Genie 3 represents a groundbreaking development in the field of AI-driven 3D world modeling. By bridging the gap between text descriptions and interactive virtual environments, Genie 3 empowers users to bring their ideas to life in ways that were previously unimaginable. This technology heralds a new era of creativity, innovation, and exploration in the digital realm, shaping the future of AI-driven experiences for years to come.